From Advice to Production: Why Forward-Deployed Engineering Is Replacing Consulting
- Oct 16, 2026
Forward-Deployed Engineering | By the Zylen Solutions Team | 3-minute read
Here is a hiring trend worth noticing. Between January and August 2026, job postings for forward-deployed engineers grew by more than 1,000% compared with the same months a year earlier, according to Lightcast data reported by Fortune. The roles also pay well: a median advertised salary above $188,000, versus about $145,000 for software engineers.
Behind the number is a simple shift. Most companies are no longer short of AI ideas or AI experiments. They are short of people who can take an experiment and make it run reliably on real systems, with real data and real limits.
The limits of advice
Classic consulting delivers a recommendation. An expert team looks at the problem, weighs the options and presents a clear way forward. When the question is "what should we do?", that is valuable.
Getting AI into production asks a different question: "how do we make this work here?" The answer depends on details you only see from the inside, such as how traffic actually behaves, which requests could run on a cheaper model, or where sensitive data leaves the building. Those details live in code, pipelines and cloud accounts, so that is where the work has to happen.
Four differences that matter
- Location: the team works in your repositories and infrastructure, not in workshops.
- Output: changes running in production, rather than a set of recommendations.
- Evidence: a before-and-after measured on your own data, rather than a progress update.
- Legacy: code, tests and runbooks your team keeps, rather than a document on a shared drive.
Our approach
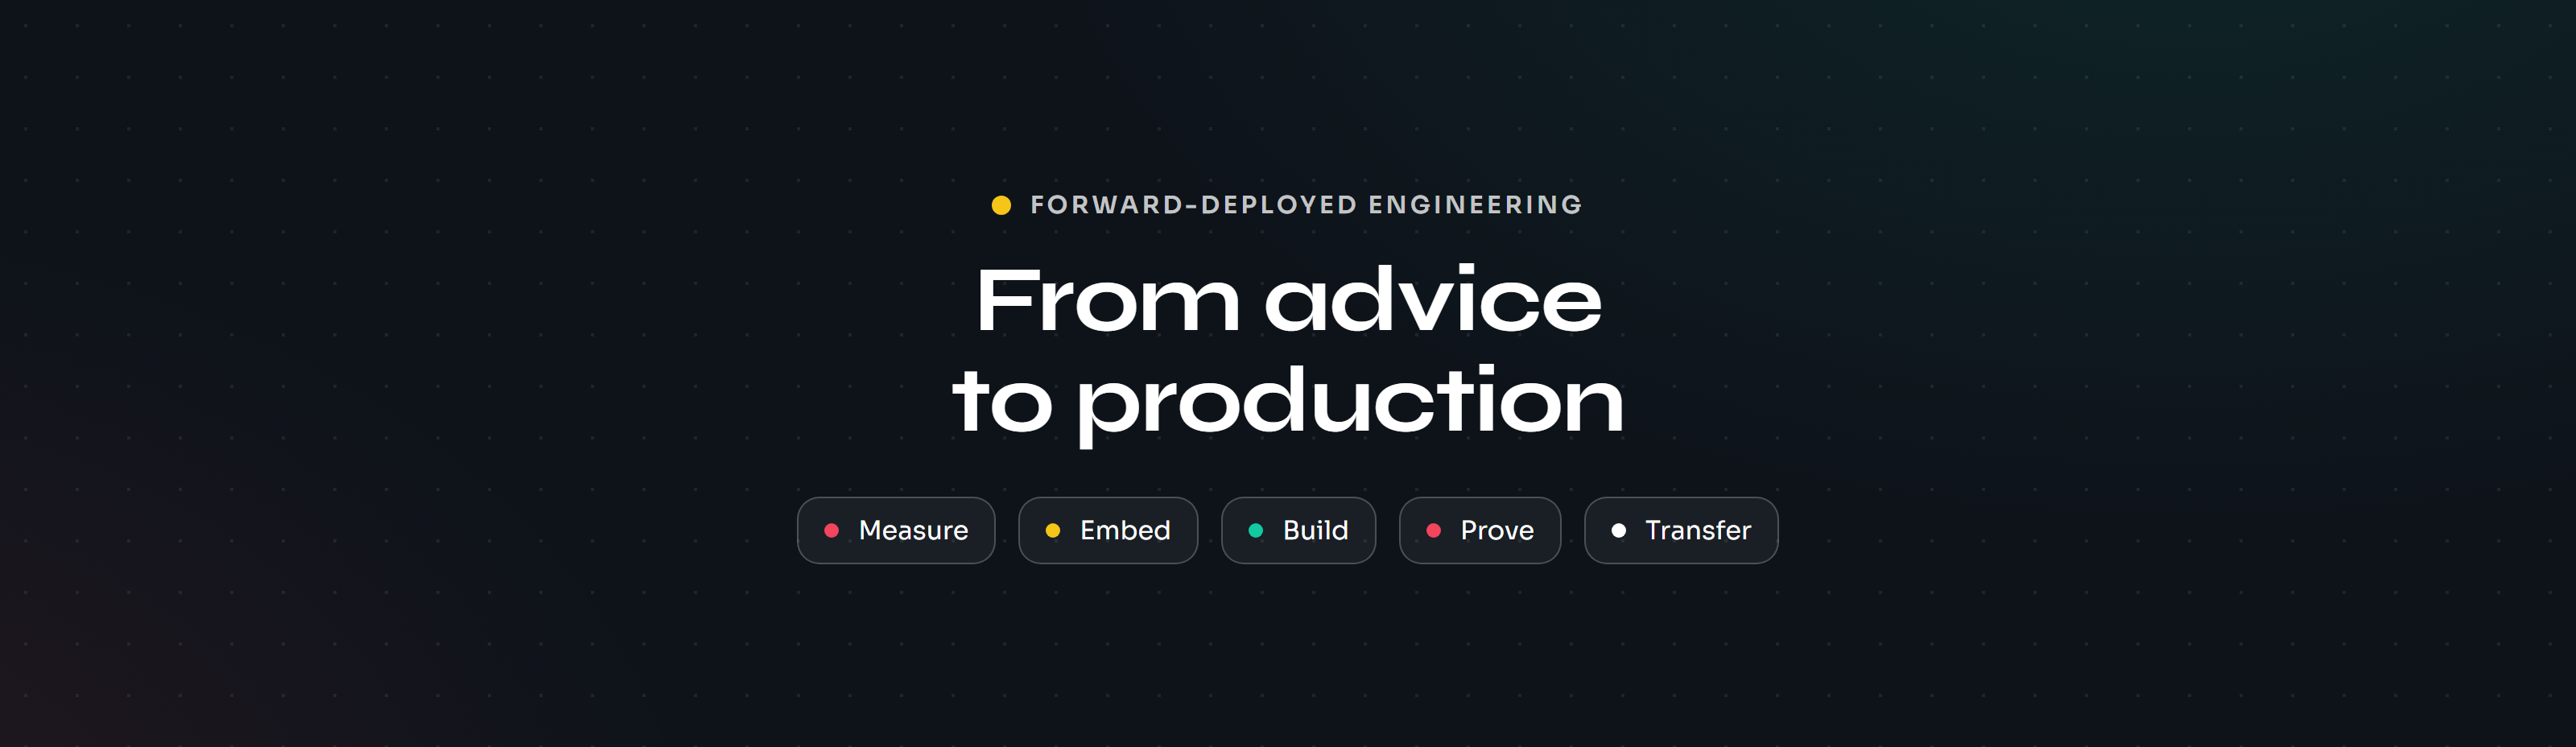
Zylen delivers through forward-deployed engineers who work on the AI a company already runs. Each engagement follows the same five steps:
- Measure. Record cost per call, latency, quality and data boundaries before changing anything.
- Embed. Work in your standups, tools and release rhythm.
- Build. Ship small changes every week against real traffic, behind a flag.
- Prove. Compare results on your own test cases before and after. If the numbers don't hold, the change stays out.
- Transfer. Leave the code, the evaluations, the runbooks and the backlog with your team.
Choosing between the two
Both models have their place. Consultants are the better fit when you are still setting direction and want a view across the whole business. Forward-deployed engineers are the better fit when a pilot won't make it to production, or when AI spend keeps climbing and nobody can explain it.
A low-risk first step
You can test the model without a long commitment. Our ten-day AI Optimization Audit maps what your AI workloads cost and expose, ships one measured change in your environment, and gives you the results.
Pay for results, not recommendations: start the AI Optimization Audit
Source: Preston Fore, Fortune, Sep 3, 2026, citing Lightcast data.
About Zylen
Zylen is an engineering firm working on AI cost, security and sovereignty. We meter what inference actually costs, put guardrails in front of AI systems, and run open models inside our customers' own infrastructure.
Recent Posts
Read-Only First: How to Roll Out Agents Inside Legacy Systems Without a Security Incident
Build vs Buy vs Embed: How to Pick the First AI Use Case Inside a Real Company
From Advice to Production: Why Forward-Deployed Engineering Is Replacing Consulting
Why Offline Evals Lie: Building Eval Users That Behave Like Real Ones
Categories
- AI Engineering
- AI Cost Optimization
- Company News
- Healthcare IT
Newsletter
Contact us
Have a project in mind? We would love to hear from you.
Send